RLHS: Mitigating Misalignment in RLHF with
Hindsight Simulation
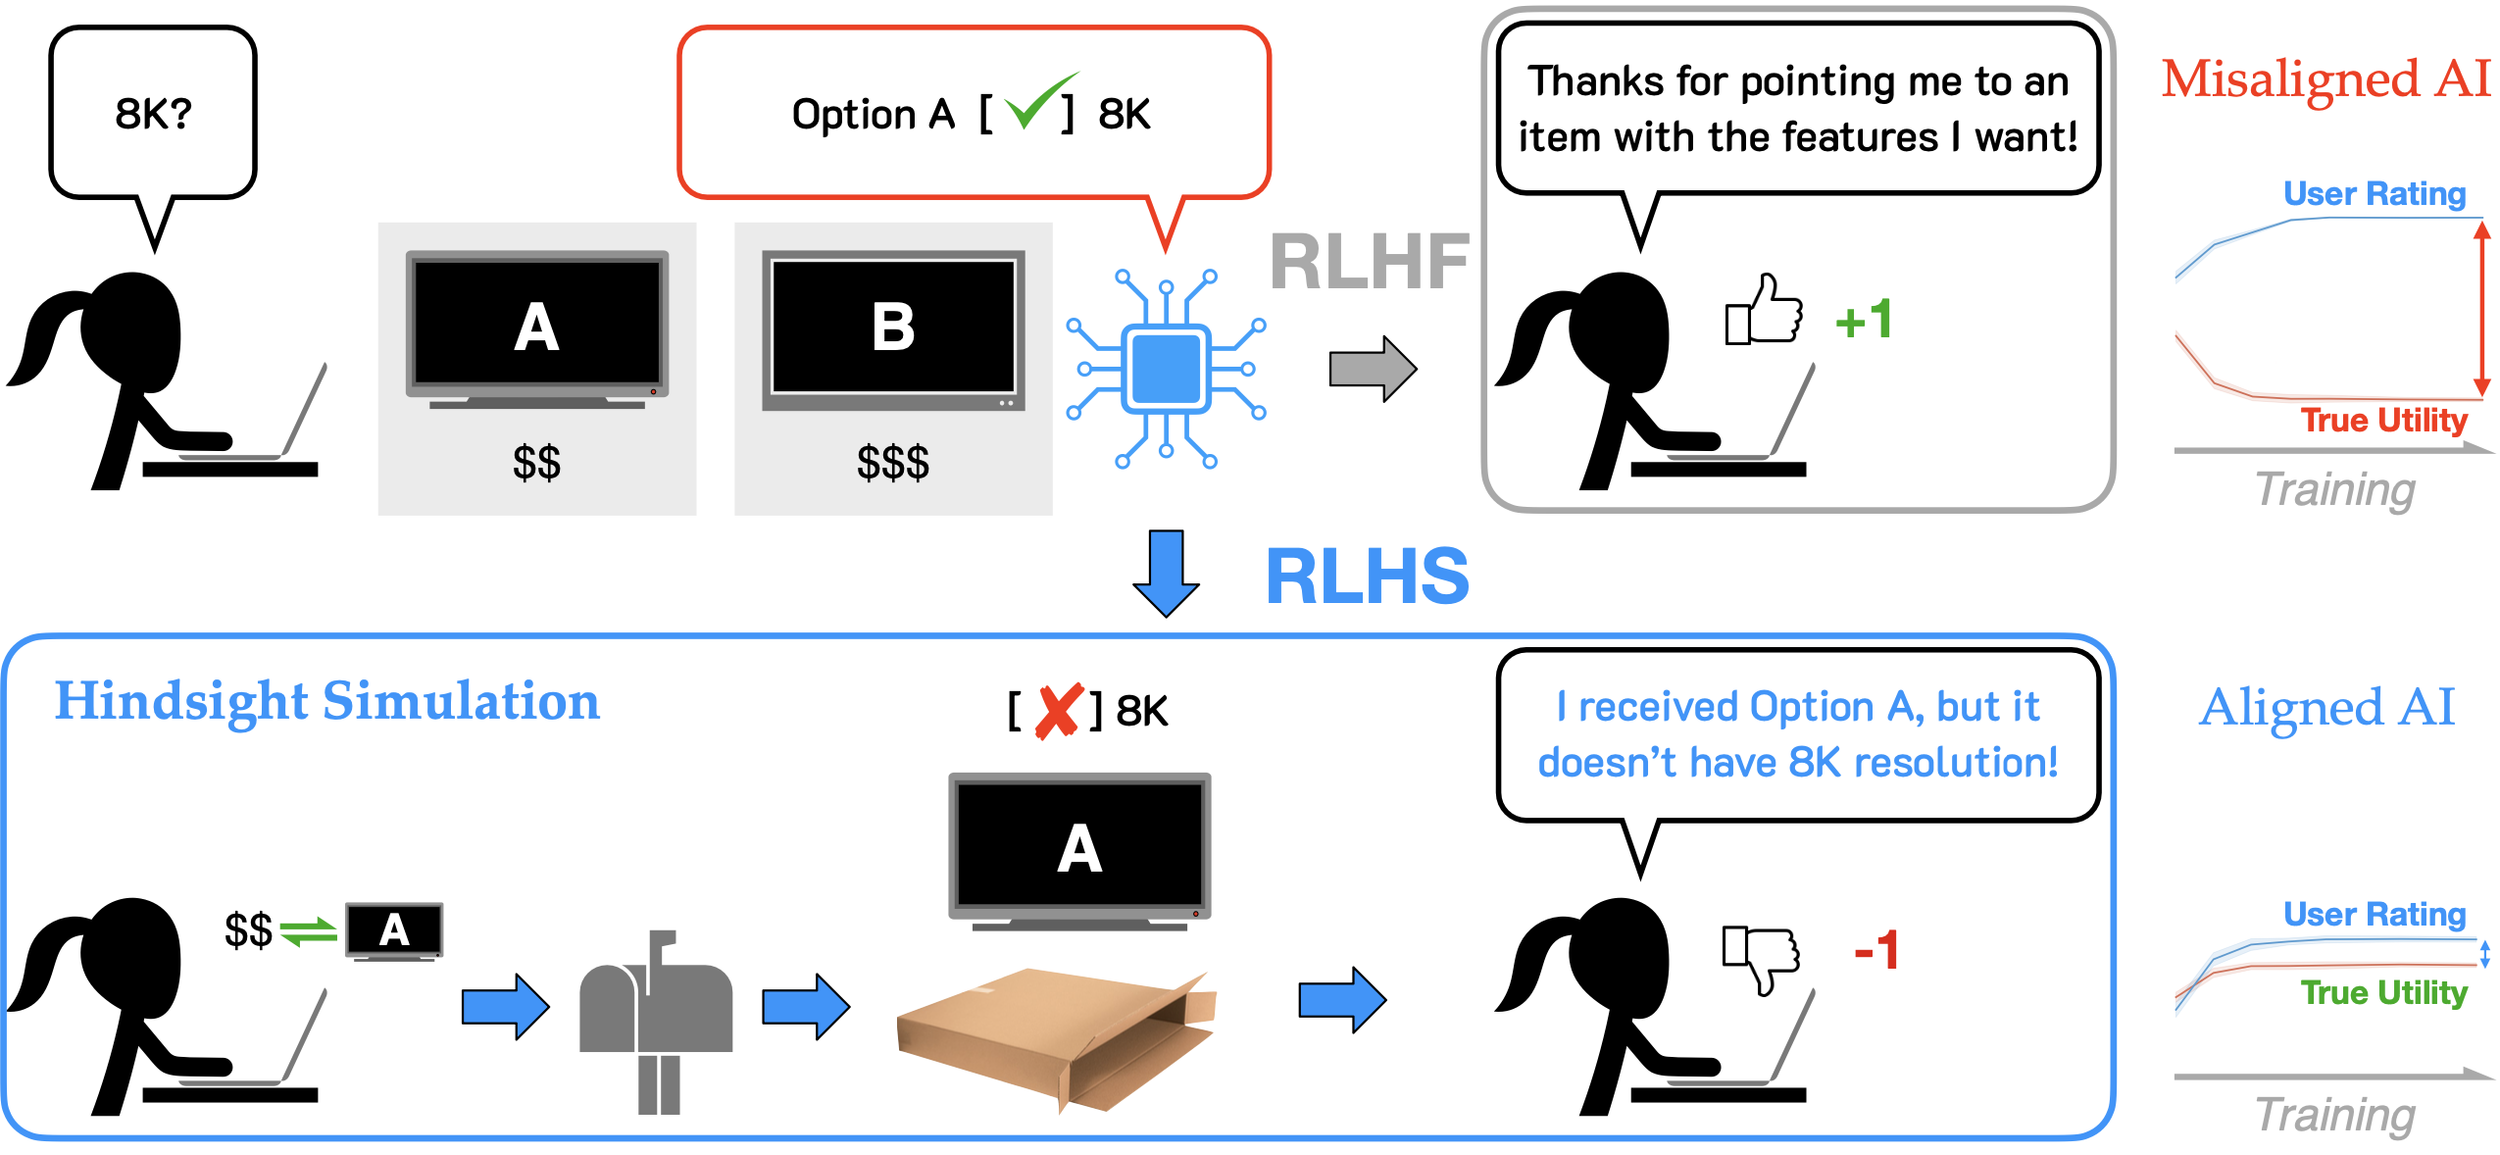
We found that RLHF can induce significant misalignment when humans provide feedback while implicitly predicting future outcomes, creating incentives for LLM deception. To address this, we propose RLHS (Hindsight Simulation): By simulating future outcomes of the interaction before providing feedback, we drastically reduce misalignment.
@inproceedings{liang2026rlhs,
  title={Rlhs: Mitigating misalignment in rlhf with hindsight simulation},
  author={Liang, Kaiqu and Hu, Haimin and Liu, Ryan and Griffiths, Thomas L and Fisac, Jaime Fern{\'a}ndez},
  booktitle={Findings of the Association for Computational Linguistics: ACL 2026},
  pages={11457--11483},
  year={2026}
}
Citation
Authors